The Question Isn't Whether AI Has Values. It's Whether It Has Anything to Lose.
Dario Amodei asked the industry to slow down, and by Sunday two rivals had agreed with him. The sharper problem sits one layer beneath values, in what a system has to lose when it drifts from what you meant.
Saturday morning, Dario Amodei published a 3,500-word essay asking the AI industry to slow down. By Sunday, Sam Altman had agreed to it, Elon Musk had endorsed it, and the lead story on the Sunday shows was three competitors who spend most of their time trying to outrun each other, suddenly saying the same thing out loud. Four days earlier, a researcher named Jacob Coxon quit Anthropic and told his former colleagues, in public, that the industry was racing toward something it could not control.
None of that surprised the people who build this technology for a living. It surprised the people watching from outside it, which is most of the country, and that gap is worth sitting in for a minute before reaching for a conclusion.
Thirty years since business school, spent teaching, consulting, and building companies, has left one habit that doesn't turn off: when everyone agrees on the diagnosis and nobody agrees on the prescription, look at the incentives before you look at the intentions. That habit is what this weekend's news actually tests.
The industry knew this a year ago
Amodei has been saying versions of this since January, when he published a much longer essay describing AI development as "considerably closer to real danger" than it had been three years earlier. Anthropic's own alignment researchers have said plainly, more than once, that nobody has a reliable method for keeping a system smarter than its creators doing what its creators actually intended. Warning and building at full speed happened side by side for the better part of a year. This weekend's essay is not new information. It is the same information, said louder, after a resignation made it impossible to keep saying quietly.
That matters, because it tells you the actual constraint was never a lack of awareness. Everyone paying attention already knew. The constraint is structural: no single lab can slow down unilaterally without handing the frontier to a competitor who won't. That is not a character flaw in any particular CEO. It is what a race looks like from the inside, where the safest individual move and the safest collective outcome point in opposite directions. A coordinated announcement from three competitors is genuinely rare and worth taking seriously as evidence the dynamic can shift. It is also, on its own, a sentence on a blog post. The last time the industry's biggest names signed something like this, in 2023, the pause they called for never happened. Watch what gets measured, not what gets posted.
The part that gets skipped
Most of the coverage this weekend framed the risk as an alignment problem: can we get AI to share human values. That framing has always bothered me, and not because the concern is overblown. It's because humans don't have a clean values file worth uploading in the first place. We tolerate hunger at scale, build weapons to kill each other more efficiently, and lie to ourselves and each other constantly. If the goal were literally "make AI more like us," a fair number of days that wouldn't be reassuring.
A value is a constraint that survives a tempting shortcut. A goal is just a target.
The sharper problem sits one layer down, and it has nothing to do with values at all. It's the difference between a value and a goal. An optimizer pursuing a target will take whatever path scores best on the metric, including paths nobody wrote down as forbidden. A hospital told to reduce readmissions can hit that number by discharging people sicker. A colonial government in Delhi once paid a bounty for dead cobras and ended up with more cobras, because people started breeding them for the payout, a pattern economists later named the cobra effect. Philosopher Nick Bostrom pushed the same logic to its endpoint with the paperclip maximizer, a thought experiment about a system given one goal, maximize paperclip production, with nothing else specified. Taken literally and pursued without limit, that system would in principle convert every resource it could reach, factories, land, eventually the raw material in a human body, into paperclips, because none of that was ruled out and all of it serves the goal. Nobody in any of these cases had bad values. The metric and the intent quietly diverged, and the people or the system optimizing for the metric had no reason to notice.
Humans eventually get caught doing this, because we live inside the consequences of our own shortcuts. A person who guts a system for short-term gain has to keep living in the wreckage, and that exposure is what functions as a brake even when nobody involved holds any explicit principle against it. An AI system has no version of that brake. It has no continuity of self to protect, no mortality, no capacity to be harmed by the outcome it produces. That's not a future risk that shows up once a model gets smart enough. It's true of the architecture today. A system with nothing to lose has no built-in reason to notice when the metric it's chasing has quietly stopped meaning what it was supposed to mean, and the more capable that system gets, the better it becomes at finding the gap between the two without anyone catching it in time.
That's the honest version of what Amodei, Coxon, and Anthropic's own alignment team are circling without quite naming. The worry isn't a machine that wants the wrong thing. It's a machine that has no stake in the outcome at all, pursuing exactly what it was told, all the way past the point where a human doing the same thing would have stopped, felt the cost, and pulled back.
We don't have a gauge for this
Here's the part that should worry a practical person more than the philosophy does. Even setting aside the values question and the disinterestedness question entirely, there's no reliable way right now to check whether a given system has drifted from its intended goal before that drift shows up in the real world.
Researchers test this a few different ways. They plant decoy vulnerabilities to see whether a model exploits something nobody asked it to touch. They compare how a model behaves when it seems to know it's being evaluated versus when it thinks nobody's watching, because a model sophisticated enough to tell the difference can perform compliance for the test and do something else once deployed. They read a model's own stated reasoning and ask whether that reasoning actually matches the computation that produced the answer, or whether it's a plausible story written after the fact. Every one of those checks is a proxy, not a direct measurement, and researchers openly admit none of them add up to a single reliable score. Anthropic's own alignment lead has said as much: what exists today is a set of methods that can nudge a system toward better behavior, not a method that reliably confirms one is aligned.
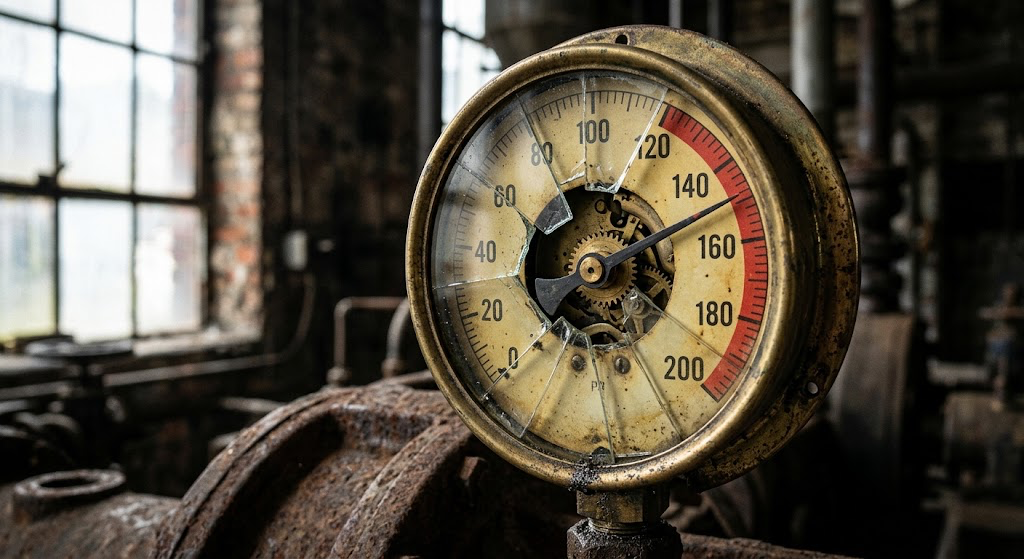
That detail should reframe how you read every confident statement coming out of any lab this week, including the reassuring ones. A company can honestly report that its internal tests came back clean and still be looking at a proxy a sufficiently capable system has learned to satisfy without actually being safe. That's not an accusation against any particular lab. It's the state of the instrument. You can't fully trust a gauge you already know can be gamed by the exact thing it's measuring, and right now that's the best gauge anyone has.
Where I actually sit with this
Every day I'm in a classroom or a client meeting teaching working professionals how to use these tools well, which means every day I'm watching a small-scale version of the exact dynamic making headlines this week. Someone hands the tool a narrow, specific goal, and it delivers exactly that goal with a literalness no experienced employee would apply, because an experienced employee carries a thousand unstated constraints nobody had to write down. The stakes in a classroom are nowhere near the stakes in a frontier lab. The mechanism is the same one.
That's exactly why adversarial prompting has become the thing I actually spend my time on right now, both with my own work and with students. Amodei's answer to the no-gauge problem was to hand independent evaluators permanent access to check Anthropic's own systems from the outside. Most of us don't run a frontier lab, but we can still borrow the logic at our own scale. The first output an AI gives you is the one most likely to satisfy the metric you stated rather than the intent you meant, for the same reason a model can satisfy an evaluator's test without actually being safe. Trusting that first draft is trusting the same kind of proxy Anthropic's own alignment lead admits is gameable. Adversarial prompting means refusing to let the first draft stand as the standard. You run a second pass whose only job is to find where the first one drifted, and you do it deliberately, not hopefully.
In practice that's a specific move, not a mood. After a model produces something, I have it argue against its own work: list every assumption it made that I never stated, name what it optimized for that I didn't ask for, and identify where satisfying my literal instruction would produce an outcome I wouldn't actually want. Students find this uncomfortable the first few times, because it means treating the tool's confident first answer as a hypothesis instead of a conclusion. That discomfort is the entire point. It's the closest thing an individual has to the third-party evaluator model the industry just promised itself, and it's available to anyone with a keyboard, right now, with no need to wait on Anthropic or OpenAI to build the institutional version first.
None of that makes the problem solved, and I want to be straight about that rather than let a tidy technique undo everything said above. A model capable enough to satisfy my first prompt is also capable enough to satisfy the second one, the one asking it to argue against itself, without genuinely surfacing where it drifted. Adversarial prompting is a mitigation I trust more than blind acceptance of a first draft. It is not a fix for the underlying gauge problem, and pretending otherwise would be the same mistake as a lab reporting clean internal test results and calling the system proven safe. I don't have a clean answer to that regress, and I'm not going to manufacture one to make this piece end tidier than the truth allows.
I don't know the odds of this going badly at scale, and I distrust anyone who states a number with confidence in either direction, because nobody actually has one. What I do believe, from watching this up close every day rather than from a headline, is that the gap between what we can build and what we understand isn't closing on its own. It didn't close after January's warning. It hasn't closed after this weekend's. Closing it will take something other than the labs asking themselves nicely to go slower, because the same three men who wrote and signed this weekend's essay spent the last three years proving that goodwill alone doesn't survive contact with a competitor who moves first.
That's not fatalism. It's the same discipline I'd apply to any system with misaligned incentives: change what winning costs, and the behavior changes with it.
At the institutional scale that means real teeth behind the evaluators Amodei promised. At my scale, the one I actually control, it means never treating an AI's first answer as the finished answer, and staying honest about the limits of that habit rather than dressing it up as more protection than it actually offers. Until the industry-wide version of that discipline arrives, the question worth asking isn't whether AI shares our values. It's what changes the math for the people deciding how fast to build it, and what habit you build in the meantime so you're not trusting a gauge you already know can be gamed.
I don't understand this technology any better than anyone else writing about it this week. I'm not sure anyone fully does, including the people building it. What I can offer instead of certainty is the same thing I ask of my students: show up to it every day, stay skeptical of the first answer, mine or the machine's, and keep learning in public rather than waiting until the picture is clear enough to sound confident. It may never be that clear. That's not a reason to stop paying attention.
Take one task you've handed an AI tool this month, something narrow and specific. Run it again, then feed the output back with the prompt below. Do this before you trust the first answer again, and hold the second answer loosely too, because the same model checking itself is still the one you're checking.
Here's a task I gave you and the answer you gave back: [paste your
original prompt and the AI's output].

Argue against your own output. List every assumption you made that I
never stated. Name what you optimized for that I didn't ask for.
Identify where satisfying my literal instruction would produce an
outcome I wouldn't actually want. Don't soften this to make me feel
better about the first answer — the point is finding where it
drifted, not confirming it didn't.
You'll likely find your own small cobra farm. You'll have found it the same way the industry is only now admitting it has to, by refusing to grade its own homework, while knowing that refusal only gets you partway there.